Archive-Scale Infrastructure Plan-Set Data Extraction

Transforming Historical Engineering Archives into Structured, Searchable Assets with Field-Level Confidence Scoring

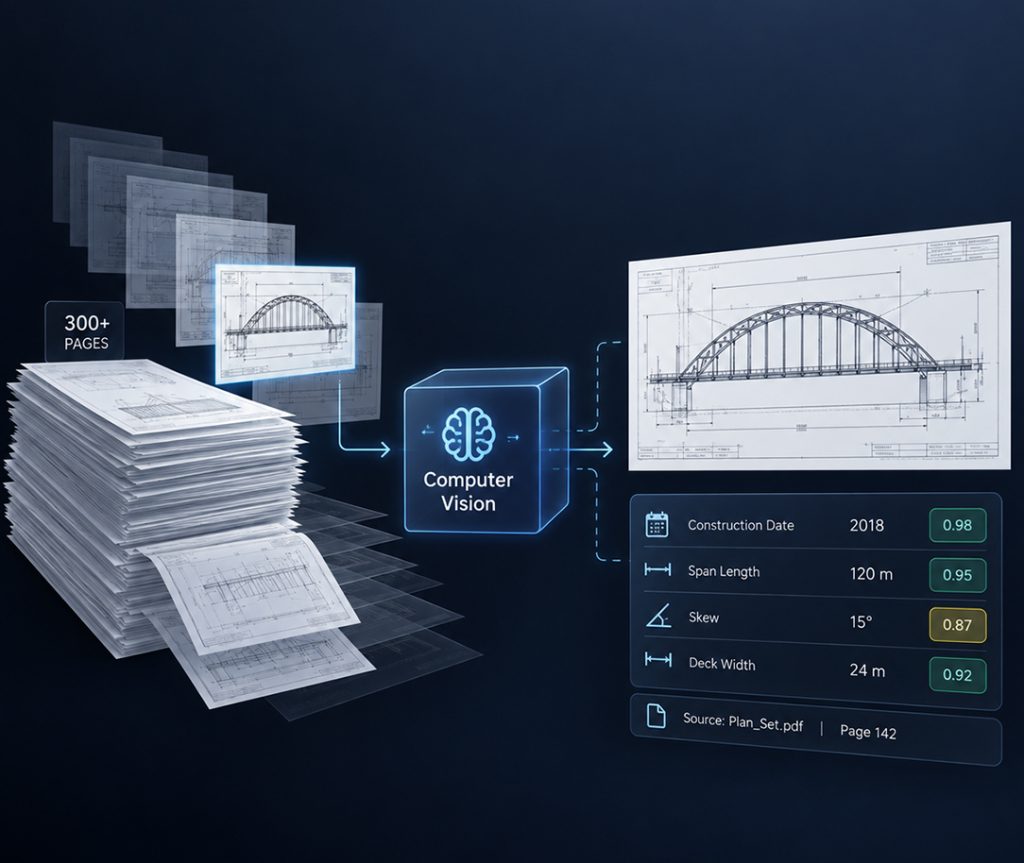
A leading US infrastructure firm needed to convert over a century of bridge plan sets into a structured database. By deploying a specialized computer vision pipeline, they automated archive-scale data extraction across 4,000+ bridges with field-level precision. 

Challenges

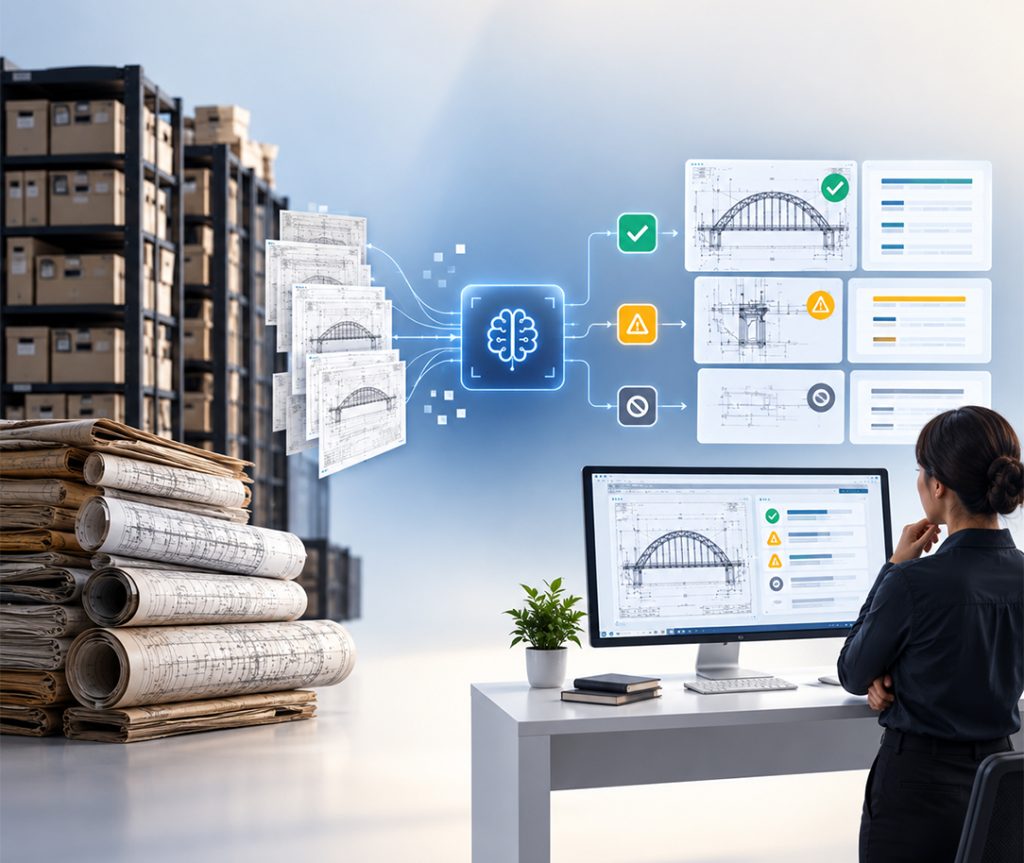
  • Unstructured Historical Archives: Managing over 4,000 bridges and 8,000+ plan-set PDFs dating back to 1890, often running up to 390 pages per set with no extractable text layer.
  • Inconsistent Reading Order & CAD Layers: Modern CAD sheets (2015+) failed standard OCR/text layer extraction due to non-sequential reading order of dimension text. 
  • Dangerous AI Hallucination: Standard LLMs extracted figures with false confidence (e.g., misreading hand-drawn dimensions like 5′-8″ without signaling error), creating safety risks.

The Solution

Deployment of a specialized computer vision pipeline engineered to treat every sheet as a visual drawing, incorporating intelligent page triage and field-level uncertainty flags.

Business Outcomes & Impact